“AI understands your whole codebase” is usually shorthand for something more precise: a retrieval and exploration system deciding which tiny parts of the codebase the model should actually see.
In the first article in this series, we looked at why AI coding assistants hallucinate and why better context is often more valuable than simply providing more context.
That raises an obvious question:
How does an AI coding assistant decide which parts of your codebase belong in its context?
When Cursor, Aider, or Claude Code appears to “understand your repository,” the underlying language model is not necessarily reading every file in your project.
Instead, the coding tool sits between the model and your repository. Its job is to help the model answer questions such as: which files are relevant to this task, where a function is defined, what calls this service, which implementation should be reused, what architectural patterns already exist, and which files should be inspected before making a change.
Different coding tools approach this problem differently. Understanding those differences explains why the same model can behave very differently depending on the environment in which you use it.
The model does not automatically know your repository
Suppose your application contains 5,000 files and you ask:
Add support for cancelling a subscription.
A developer familiar with the project might immediately know that the relevant code lives in:
apps/api/subscriptions/
packages/billing/
packages/database/
But an AI model starts with no such intuition unless the coding environment provides it. The tool therefore needs to discover relationships such as:
cancelSubscription()SubscriptionServiceBillingProviderStripeBillingProvidersubscription repository
Once those relationships have been discovered, the actual model may only need a handful of files. That is the core problem these tools are solving:
How do we reduce a large repository into the smallest useful set of context for the current task?
Approach 1: Search the repository
The simplest approach is surprisingly powerful: search for something relevant, inspect the results, then search again.
Imagine an agent receives “Find where subscriptions are cancelled.” It might search for cancelSubscription. If nothing useful appears, it might broaden the search to subscription, cancel, stripe, and billing. Then it reads the promising files and follows references from there.
This closely resembles how a developer explores an unfamiliar project. Modern coding agents are increasingly good at this iterative process. They do not necessarily need a perfect representation of the entire repository before starting. They need tools that let them progressively discover the repository.
Cursor: From semantic indexing toward agent driven search
Cursor became well known for codebase indexing. Historically, one important part of that system involved breaking source files into chunks and generating vector embeddings for semantic search.
Embeddings allow conceptually related code to be found even when the exact words in the user’s prompt do not appear in the source code. A developer might ask “Where do we validate customer permissions?” while the code itself contains terms such as authorizeUser, AccessPolicy, and PermissionGuard. Semantic retrieval can identify relationships that simple text matching may miss.
Cursor has publicly described an indexing architecture where files are divided into syntactic chunks and transformed into embeddings. It has also described using Merkle trees—hierarchical structures of cryptographic hashes—to determine which files changed so that unchanged parts of a repository do not need to be processed again. Cursor, “Securely indexing large codebases”
That architecture is interesting, but it also demonstrates how quickly AI coding tooling evolves. In July 2026, Cursor staff explained that its agents had increasingly moved away from the older dedicated semantic search path because modern models had become much better at using grep style and indexed search. Cursor described its newer approach as leaning on Instant Grep and normal file reads, while still respecting repository ignore rules for those searches.
That change reveals something important. The industry is discovering that sophisticated retrieval infrastructure is not always required for every query. Sometimes a capable agent repeatedly searching and reading the repository can outperform a system that tries to predict all relevant context in advance.
What Cursor’s approach teaches us
The important lesson is not whether embeddings or grep are “better.” It is that retrieval strategies can change as models become more capable.
A system may combine:
- indexed search
- exact text search
- file discovery
- editor state
- manually referenced files
- project rules
- terminal commands
- previous conversation context
The model then decides which information to inspect next. That is much closer to interactive investigation than simply sending a database query and placing the results into a prompt.
Aider: Build a map before you need the road
Aider takes a particularly interesting approach to repository context. Instead of placing the complete contents of every source file into the model’s context, Aider constructs a compact repository map.
The map includes important information such as:
- filenames
- classes
- functions
- methods
- types
- call signatures
- important definitions
A simplified map might look conceptually like this:
src/payments/service.ts
│
├── class PaymentService
│   ├── createPaymentIntent(customerId, amount)
│   └── refundPayment(paymentId)

src/subscriptions/service.ts
│
├── class SubscriptionService
│   ├── createSubscription(customerId, planId)
│   └── cancelSubscription(subscriptionId)
The model can now see that these abstractions exist without receiving every line of their implementations. Aider’s documentation describes its repo map as a concise representation of the Git repository containing important classes, functions, types, signatures, files, and critical definition lines. aider, “Repository map”
Tree sitter: Extracting structure from source code
To construct repository maps across many programming languages, Aider uses parsing infrastructure built around Tree sitter. Tree sitter produces syntax trees from source code.
export class PaymentService {
  async refundPayment(paymentId: string) {
    // implementation
  }
}
A syntax parser can identify that this code contains:
class: PaymentService

method:
  name: refundPayment
  parameter: paymentId
  type: string
That structural information is much more compact than sending the entire file. It also gives the model something extremely valuable: the vocabulary of the repository.
Before writing a new payment abstraction, the model can discover that PaymentService already exists. Before inventing a helper function, it can see that another module already exposes the capability it needs. This directly reduces one of the most common AI coding problems: creating new code that duplicates existing abstractions.
But even a repository map can become too large
Imagine a monorepo containing tens of thousands of symbols. Even a compressed list of every class and function may exceed a sensible context budget.
Aider therefore ranks the repository map. Its documentation describes building a graph where repository files are nodes and dependencies form connections between them. A graph ranking algorithm is then used to determine which definitions are most important and relevant to the current conversation. aider, “Repository map”
The tool can then spend its context budget on a small subset of the repository map. By default, Aider documents a repo map token budget of roughly 1,000 tokens, although it adjusts this dynamically depending on the state of the conversation.
Think about what that means. A repository may contain hundreds of thousands of lines of code. But the model initially receives something closer to an architectural index. If it then determines “I need to inspect SubscriptionService,” the relevant implementation can be added to the active context.
Map first, details second.
Claude Code: Let the agent explore
Claude Code takes another approach. Rather than depending primarily on a pre generated structural map, Claude Code gives the model tools for exploring the repository directly.
Its current toolset includes capabilities for:
- finding files with glob patterns
- searching file contents
- reading files
- editing files
- running shell commands
- running tests
- using Git
- inspecting diagnostics
- spawning specialized subagents
Claude Code’s documentation describes this as an agentic loop: each tool call produces new information, and that information determines what the agent does next. Claude Code docs, “How Claude Code works”
For example, given “Fix the checkout failure when a card has expired,” an agent might perform something like:
The context is being constructed during execution. That is fundamentally different from trying to determine the complete context before the model begins reasoning.
Search agents can use their own context windows
Large repository exploration creates another problem. Imagine the main coding agent reads 30 files while trying to understand your authentication system. Even if it eventually discovers the answer, all that investigative material can pollute the main conversation.
Claude Code now addresses this partly through specialized subagents. Its built in Explore agent is designed specifically for read only file discovery and codebase investigation. It operates with its own context and returns findings to the main agent rather than requiring every exploratory file read to remain in the main conversation. Claude Code docs, “Create custom subagents”
Delegates: “Investigate authentication flow.” Receives a summary, then edits with a smaller, cleaner context.
- searches files
- reads implementations
- follows references
- produces findings
This is a powerful context management pattern. Instead of one enormous context accumulating everything the system has ever inspected, separate agents can work with isolated context windows and return only the useful result. Claude’s documentation explicitly recommends using subagents for large codebase exploration so that the main context is not filled with all of the intermediate file reads. Claude Code docs, “Common workflows”
Three tools, three different strategies
We can simplify the comparison like this:
| Tool | Important context strategy | Basic idea |
|---|---|---|
| Cursor | Agent driven search, indexed retrieval, file reads and editor context | Search for relevant code and progressively inspect it |
| Aider | Structural repository map plus selected files | Give the model a compact architectural map before loading implementation details |
| Claude Code | Tool driven exploration and subagents | Let the model actively investigate the repository and build context as it works |
This table is intentionally simplified. Modern coding tools increasingly combine several techniques, and their implementations change rapidly. That is actually the more interesting trend.
IDE vs. CLI is becoming the wrong comparison
A few years ago, it was easy to think of these tools as two categories: IDE assistants versus terminal assistants. That distinction is becoming much less useful.
Cursor now has increasingly autonomous agents and terminal capabilities. Aider can work alongside editors. Claude Code is available beyond the terminal, including IDE, desktop, and web environments. Claude Code docs, “Overview”
What matters more is the agent’s context architecture. When evaluating an AI development tool, better questions are:
How does it discover relevant code?
Exact search, semantic retrieval, structural maps, language intelligence, or some combination?
How much context does it load?
Does it send large amounts of source code immediately, or retrieve code progressively?
Can it follow relationships?
Can it identify definitions, references, dependencies, and existing abstractions?
Can it isolate exploration?
Can separate agents investigate different parts of the repository without filling the primary context?
Can it verify its assumptions?
Can it run tests, inspect compiler errors, execute the application, or examine runtime output?
These questions tell you far more about how reliable an AI coding environment will be than whether it happens to run inside an IDE or a terminal.
The real architecture is a feedback loop
The most capable coding assistants are increasingly converging on a similar pattern:
That looks remarkably similar to how experienced developers work. A developer rarely understands an unfamiliar repository by opening every file. They form a hypothesis. They search. They inspect a few files. They follow a dependency. They make a change. Then they run the software or tests to see whether their understanding was correct.
AI agents are becoming more reliable as their tooling enables the same process.
Why this matters for your own codebase
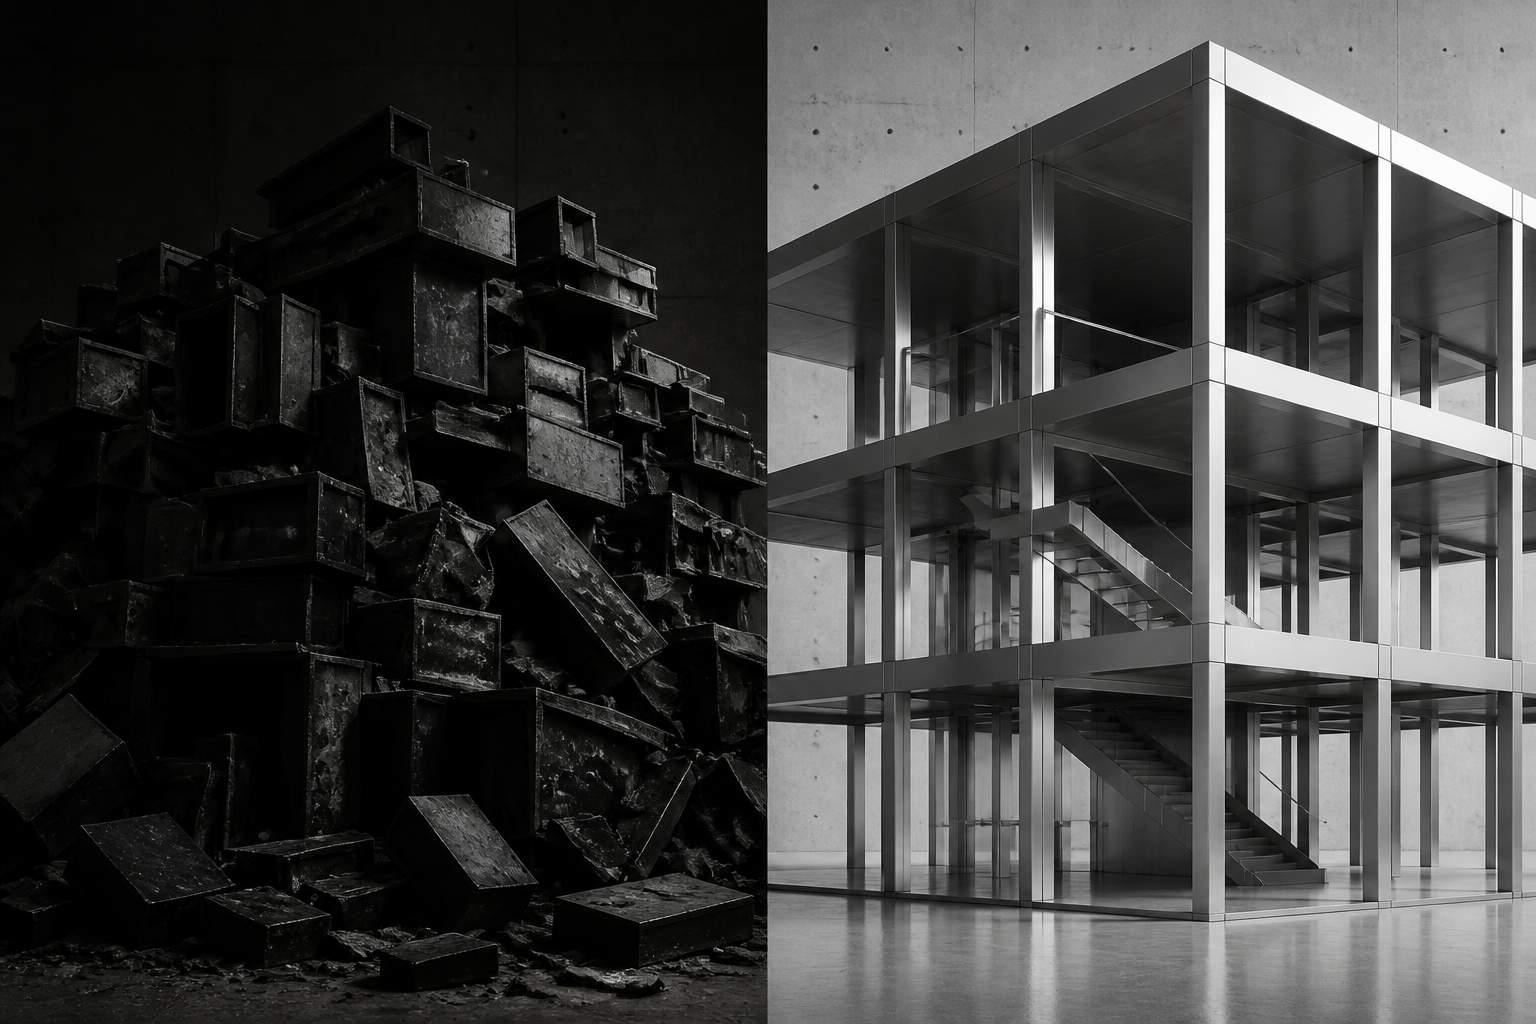
There is another implication that is easy to miss. If AI agents depend heavily on repository exploration, then the structure of your software directly affects how well AI can work with it.
utils2.ts
helpers final.ts
misc.ts
new service.ts
temp.ts
Duplicated business logic and inconsistent naming.
billing/
  BillingService.ts
  BillingRepository.ts
  StripeBillingProvider.ts
  billing.test.ts
Clear interfaces and predictable responsibilities.
Which repository will an agent understand more reliably? Almost certainly Project B. Good software architecture was already valuable for humans. AI assisted development gives us another reason to care about it.
Clear names, explicit interfaces, predictable boundaries, small modules, reliable tests, and good documentation make a repository easier for both humans and machines to navigate.
The key principle
AI coding assistants do not need perfect knowledge of your entire repository. They need an effective way to discover the small amount of information that matters for the decision they are currently making.
Cursor demonstrates how search and retrieval strategies can evolve as models improve. Aider demonstrates the power of giving a model a compact structural map of a repository. Claude Code demonstrates how an agent can progressively build context by searching, reading, delegating research, executing code, and responding to the results.
Different architecture. Same objective:
Find the right code before changing the code.
And that leads to the next problem. Even if an agent can find the correct files, how does it know the rules of your project? Where should business logic live? Which commands should it run? Which files must never be modified? What conventions should it follow?
That is where repository level instructions become important.
AI does not make software architecture less important.
The interesting lesson from all three tools is that it makes good architecture easier to recognize. A well structured application gives developers—and AI agents—clear paths through the system. Services have defined responsibilities, dependencies are understandable, tests provide feedback, and new functionality has an obvious place to live.
That matters whether you are building a SaaS platform, a Shopify application, an internal business system, an AI enabled product, or enterprise software.
We design and build software with those foundations in mind: clear architecture, maintainable code, reliable integrations, automated testing, and systems that can continue evolving after the first release.
If you are planning a new software product or trying to modernize an application that has become difficult to change, get in touch to discuss the architecture before complexity becomes the most expensive part of the project.
Get in touch